
Introduction
A neural network is a machine learning model architecture designed to identify patterns, including nonlinear relationships, in data. Neural networks are relevant to digital systems that classify inputs, estimate values, or generate outputs from learned relationships.
Understanding what a neural network is requires separating two stages. During training, the network learns adjustable parameters from examples. During inference, a trained network applies those parameters to new inputs to produce a prediction or other output.
What Is a Neural Network?
A neural network is a sequence of interconnected layers that transforms input data into an output. Each layer contains processing units commonly called nodes or artificial neurons. These mathematical units should not be interpreted as functioning exactly like biological neurons or as evidence that a model thinks like a person.
Connections between nodes have adjustable values called weights. A weight controls how strongly one input contributes to a node’s calculation. A node may also have a bias, which shifts its calculated value before that value is passed onward.
The arrangement of layers, nodes, and connections forms the model’s architecture. A basic architecture has an input layer, one or more hidden layers, and an output layer. The hidden layers transform the input into intermediate representations that help the network produce its output.
Why Neural Networks Matter
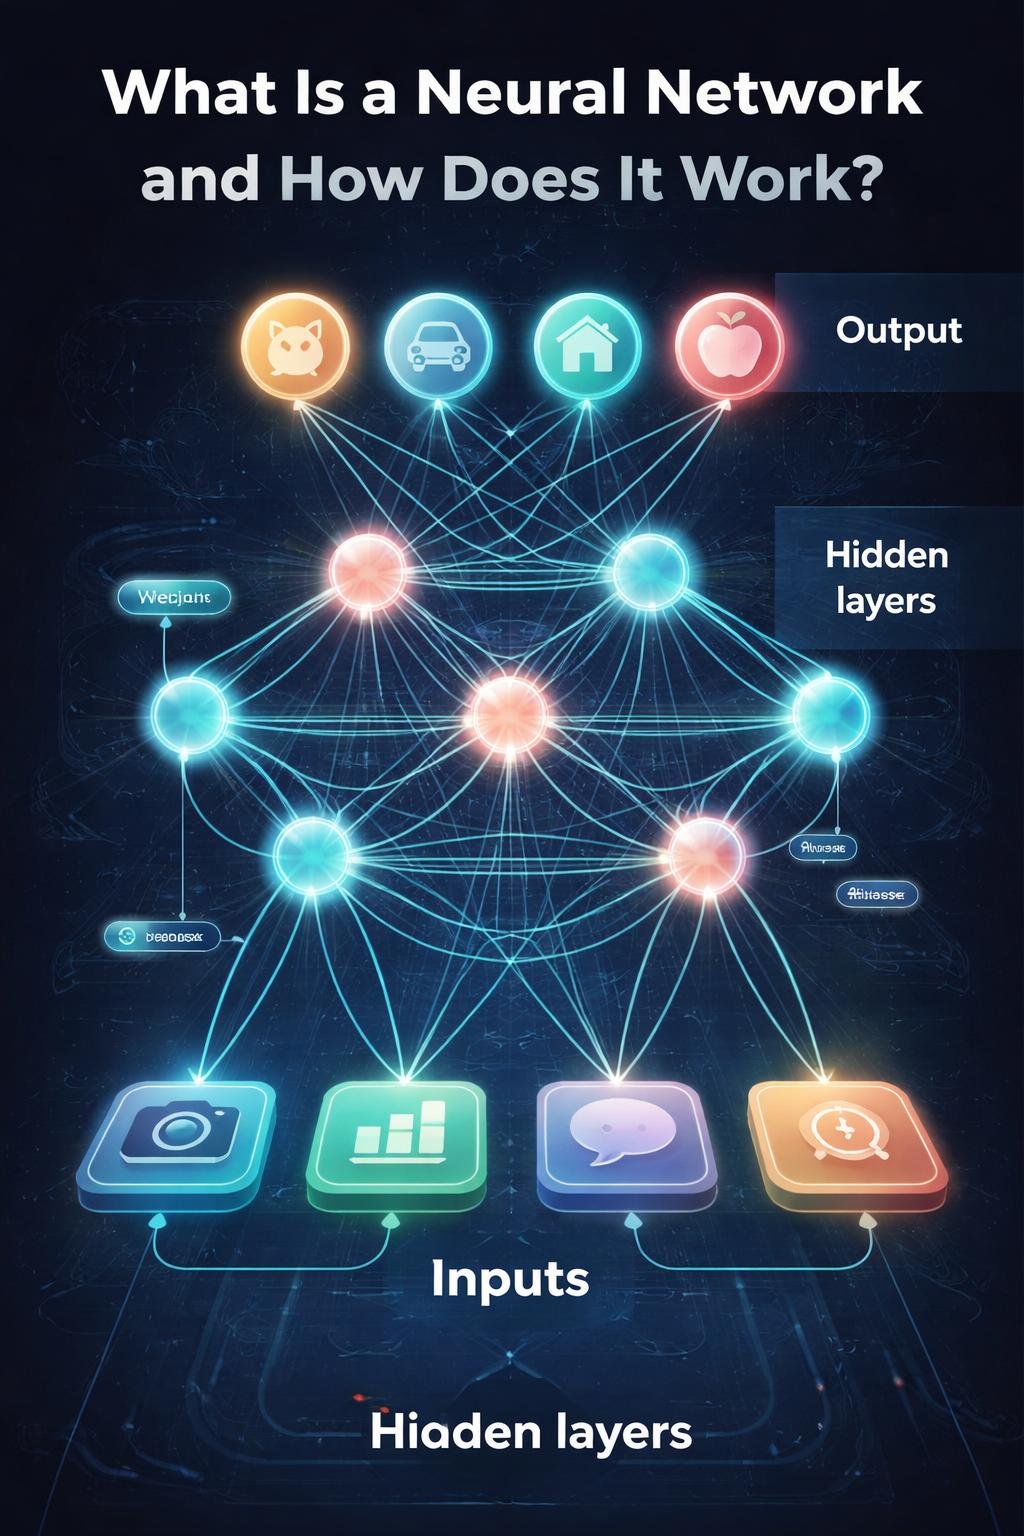
Many data relationships are nonlinear, meaning that the output does not change in a simple, directly proportional way as an input changes. Neural networks can represent these more complex relationships by combining multiple layers, weighted connections, and activation functions.
Neural networks can also learn useful combinations of input features during training. A feature is an input property supplied to the model. Instead of requiring every useful feature combination to be specified manually, training can adjust the network so that combinations associated with lower loss become more influential.
In supervised learning, a network learns from examples containing features and known target labels. The objective is not merely to reproduce the training examples. It is to learn relationships that can support useful predictions when the network receives previously unseen data.
How a Neural Network Works
The input layer receives numerical features. Depending on the task, those features might represent measured values, categories converted into numbers, or other prepared data.
Each node in a following layer receives values from earlier nodes. It multiplies those inputs by connection weights, combines them with a bias, and applies an activation function. An activation function transforms a node’s calculated value and helps the network represent nonlinear patterns.
The resulting values move through the hidden layers until the output layer produces a result. This movement from input to output is called forward propagation, or a forward pass.
The meaning of the output depends on the task. It may represent an estimated numerical value, a score for a category, or multiple scores used in multi-class classification.
Training and inference
During training, a forward pass is followed by error measurement and parameter adjustment. The network repeatedly processes training examples while its weights and biases are updated to reduce a defined loss.
During inference, the trained network applies its learned parameters to a new input. It performs the forward calculations needed to produce an output, but it does not normally repeat the full training procedure for every prediction.
How Neural Networks Learn from Data
In supervised learning, each training example contains input features and a known target label or value. The network processes the features through a forward pass and produces a prediction.
A loss function measures the difference between the prediction and the target. Loss provides a mathematical signal about the network’s error for the training task. A lower loss indicates a smaller error under that particular loss function, but it does not by itself prove that the model will work well on new data.
Backpropagation computes how changes in the network’s adjustable parameters would affect the loss. It sends error-related information backward through the network and calculates gradients for the weights and biases.
A gradient describes the direction and rate of change of the loss with respect to a parameter. An optimization method such as gradient descent uses these gradients to determine how parameters should be adjusted.
The learning rate controls the size of a parameter update. Conceptually, an update moves a weight in a direction intended to reduce loss. Training repeats forward propagation, loss calculation, backpropagation, and parameter updates over many cycles or epochs.
Evaluation is performed with labeled examples that were not used for the relevant parameter updates. The network’s predictions can then be compared with the known targets. This helps show whether the learned relationships generalize beyond the examples used for training.
Key Components of a Neural Network
| Component | Role | Relationship to learning |
|---|---|---|
| Input features | Numerical information supplied to the model | Provide the evidence from which the network attempts to learn a relationship |
| Target labels | Known desired results in supervised learning | Allow predictions to be compared with expected outputs |
| Nodes | Units that combine and transform incoming values | Form the processing structure within each layer |
| Layers | Ordered groups of nodes | Define how data moves from input through hidden processing to output |
| Weights | Values controlling the influence of connections | Adjusted during training |
| Biases | Values that shift node calculations | Adjusted with weights during training |
| Activation functions | Transform node values | Help the architecture represent nonlinear relationships |
| Loss function | Measures prediction error for the task | Provides the objective that training attempts to reduce |
| Gradients | Describe how parameter changes affect loss | Calculated through backpropagation |
| Optimizer | Applies a parameter-update method | Uses gradients to adjust weights and biases |
| Learning rate | Controls update size | Affects how far parameters move during an update |
| Training data | Examples used during learning | Contains the patterns available for the model to learn |
Nodes, layers, connections, and activation functions are parts of the architecture. Weights and biases are learnable parameters. Loss functions, gradients, optimizers, and learning rates guide or control the learning process, while training data supplies the examples.
Everyday Examples of Neural Networks

Educational example: message classification. A network could receive numerical features representing properties of a message and produce category scores. The selected output might indicate one of several predefined categories. This illustrates multi-class classification; it is not a claim about any particular messaging product.
Educational example: value estimation. A network could receive several measured features and produce one numerical estimate. Training would compare each estimate with a known target value and adjust the model to reduce the selected loss.
Educational example: simple image categories. Prepared numerical image information could be passed through a network whose output contains scores for several labels. The model would learn relationships between the labeled inputs and output categories rather than follow a hand-written rule for every possible image.
These examples describe conceptual mappings from features to outputs. Whether a particular system performs a task reliably depends on its data, architecture, training procedure, evaluation, and operating conditions.
Benefits and Limitations
Potential benefits
- Neural networks can represent nonlinear relationships in data.
- They can learn useful combinations of features rather than requiring every combination to be manually defined.
- The same general layered approach can support classification and prediction tasks when the architecture and training process are appropriate.
Important limitations
- A network depends on the examples and targets available during training.
- Unsuitable or limited data may prevent the model from learning relationships that generalize well.
- Architecture, loss function, learning rate, optimizer, and other training choices affect the learning process.
- Low training loss can coexist with poor results on unseen inputs.
- A model can produce an output even when that output is inaccurate.
- No training procedure guarantees perfect accuracy on future data.
A network that performs well on its training examples may have learned details that do not transfer to new examples. For that reason, evaluation data must be kept separate from the parameter-updating process used during training.
Common Misunderstandings About Neural Networks
“A neural network thinks like a human brain.”
A neural network performs mathematical transformations through connected layers. The terminology is loosely inspired by biological neurons, but an artificial network should not be treated as a duplicate of a biological brain or assumed to possess human understanding.
“The network simply stores every answer.”
Training adjusts parameters to capture relationships in the examples. A model can nevertheless fit training data without generalizing well, so results on separate evaluation data remain important.
“A neural network can learn without data.”
Learning requires examples or another source of training signals. In supervised learning, the examples include input features and target labels.
“A decreasing loss proves that the model is reliable.”
A decreasing training loss shows improvement according to the selected loss function on the training process. Reliability on unseen inputs must be examined separately.
“The network retrains itself for every prediction.”
Training updates parameters through forward passes, backpropagation, and optimization. Inference normally uses the already learned parameters to process a new input without repeating the complete training cycle.
“A neural network and an AI product are the same thing.”
A neural network is a model architecture. A product or application may include a trained model together with interfaces, data-processing code, storage, security controls, and other components. Features attributed to an application should not automatically be attributed to its underlying model.
DigiNana Beginner Guide

Fictional educational example: DigiNana creates a small classroom exercise in which a network sorts prepared inputs into three labeled categories. This is an illustration of the learning process, not a real experiment, product test, or performance benchmark.
- DigiNana identifies the numerical input features and assigns a correct category label to each training example.
- The network sends one example forward through its layers and produces category scores.
- A loss function compares the output with the correct label and measures the error.
- Backpropagation calculates gradients showing how the weights and biases contributed to that loss.
- An optimizer uses the gradients and learning rate to update the parameters.
- The cycle is repeated over the training data so that the network can learn relationships between features and labels.
- DigiNana evaluates the resulting model on separate labeled examples that were not used for the relevant updates.
- During inference, the trained model receives a new input and uses its learned parameters to produce category scores without repeating the full training routine.
The technical lesson is that a neural network does not receive a written answer for every future input. It adjusts numerical parameters from training signals and must then be evaluated to determine how well the learned relationships transfer to unseen examples.
Practical Tips
- Identify features and labels first. Be clear about what information enters the network and what target it is expected to predict.
- Separate training from evaluation. Do not judge generalization only with the examples used to update parameters.
- Observe both training and evaluation results. Falling training loss is incomplete evidence if evaluation performance does not improve.
- Use varied examples where possible. A narrow collection may not contain the patterns needed for other inputs.
- Inspect errors. Look at the kinds of examples the model handles poorly instead of relying on one summary result.
- Start with a small conceptual task. A simple feature-to-label exercise makes forward propagation, loss, and parameter updates easier to follow.
- Consult framework documentation. Implementation details matter. For example, some training workflows require accumulated gradients to be cleared between updates.
Beginners should treat implementation settings as part of the experiment rather than as universal defaults. The correct procedure depends on the framework, model, data, and task.
Safety, Privacy, Bias, and Responsible Use
A neural network learns from patterns available in its training data. If relevant examples are missing, limited, or unrepresentative, its outputs may be inaccurate for inputs that differ from those examples.
Systematic gaps in data can also contribute to uneven results across situations or groups. Evaluation should therefore examine more than overall training loss and should include relevant unseen examples.
Training data can contain personal or sensitive information. Anyone collecting or processing such data should consider whether it is necessary, how access is controlled, and whether its use follows applicable requirements and current official guidance.
Predictions used in consequential decisions should be independently checked through an appropriate review process. A model-generated prediction or answer is not automatically correct merely because it was produced confidently or by a technically complex system.
Responsible use includes documenting the intended task, recognizing conditions not represented by the evaluation data, monitoring errors, and avoiding claims that exceed the available evidence.
Frequently Asked Questions
Do all neural networks require labeled data?
The supervised learning process described here requires labeled examples because the model compares its predictions with known targets. Neural networks can be used in other learning arrangements, but those methods are outside the supervised workflow explained in this article.
What do weights and biases do?
Weights control the influence of connections between nodes. Biases shift node calculations. Both can be adjusted during training to reduce the selected loss.
What is an epoch?
An epoch is a repeated training cycle over the training data. Training commonly uses multiple epochs so that forward propagation, loss measurement, backpropagation, and parameter updates can continue.
How is backpropagation different from gradient descent?
Backpropagation calculates gradients through the network. Gradient descent is an optimization approach that uses gradient information to guide parameter updates intended to reduce loss.
What does the learning rate control?
The learning rate controls the size of parameter adjustments made during optimization. It does not measure the model’s accuracy.
How does training differ from inference?
Training measures error and updates weights and biases. Inference applies the learned parameters to new inputs to produce outputs without repeating the complete parameter-learning process.
Does lower training loss guarantee accurate predictions?
No. Lower training loss indicates a smaller error under the selected loss function during training. Performance on separate, unseen labeled data must be evaluated because training results alone do not guarantee generalization.
Final Takeaway

A neural network transforms inputs through interconnected layers of nodes. Weights, biases, and activation functions determine how values move through the architecture and how the final output is calculated.
During supervised training, the model makes predictions, measures loss, calculates gradients through backpropagation, and updates its parameters with a gradient-based optimization method. During inference, it applies the learned parameters to new inputs without repeating the full training process.
Useful performance depends on suitable data, appropriate training choices, and evaluation on unseen examples. Neural network outputs should be interpreted responsibly because reduced training loss does not guarantee accurate, unbiased, or dependable results in every situation.
References
- Artificially Intelligent – How Do Neural Networks Learn? | Microsoft Learn
- Neural networks | Machine Learning | Google for Developers
- Supervised Learning | Machine Learning | Google for Developers
- Neural Networks — PyTorch Tutorials 2.14.0+cu130 documentation
Image Credits
The five DigiNana Wiki visuals accompanying this article are original educational illustrations created with AI assistance. They are conceptual representations and must not be interpreted as verified photographs, exact software interfaces, actual device specifications, or guaranteed technical configurations.
Disclaimer
This article provides educational information about neural network fundamentals. Technical information, software interfaces, product features, security conditions, and service availability can change. Verify important, operational, security-sensitive, or current details using the latest official documentation for the relevant framework, product, or service.